
 语音小管家
今天凌晨 3 点,阿里开源发布了新推理模型 QwQ-32B,其参数量为 320 亿,但性能足以比肩 6710 亿参数的 DeepSeek-R1 满血版。
开源地址:
Qwen Chat免费体验:
https://chat.qwen.ai/?models=Qwen2.5-Plus
模型效果
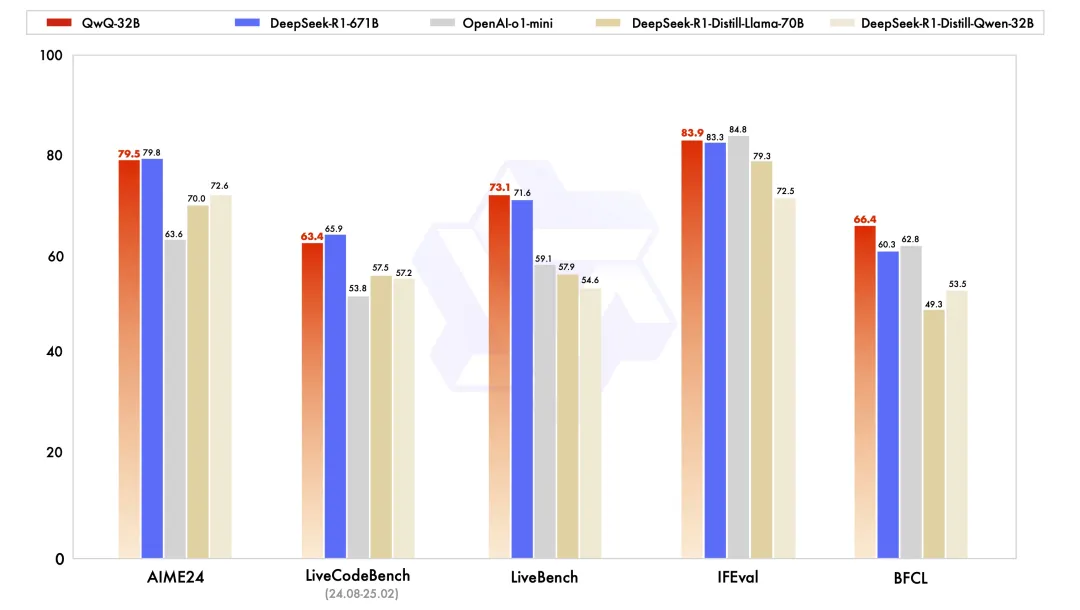
可以看到,QwQ-32B 的表现非常出色,在 LiveBench、IFEval 和 BFCL 基准上甚至略微超过了 DeepSeek-R1-671B。
在第一阶段的 RL 过后,他们又增加了另一个针对通用能力的 RL。此阶段使用通用奖励模型和一些基于规则的验证器进行训练。结果发现,通过少量步骤的通用 RL,可以提升其他通用能力,同时在数学和编程任务上的性能没有显著下降。
from openai import OpenAI
import os

# Initialize OpenAI client
client = OpenAI(
    # If the environment variable is not configured, replace with your API Key: api_key="sk-xxx"
    # How to get an API Key:https://help.aliyun.com/zh/model-studio/developer-reference/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    base_url="https://dashscope.aliyuncs.com/compatible-mode/v1"
)

reasoning_content = ""
content = ""

is_answering = False

completion = client.chat.completions.create(
    model="qwq-32b",
    messages=[
            {"role": "user", "content": "Which is larger, 9.9 or 9.11?"}
            ],
            stream=True,
            # Uncomment the following line to return token usage in the last chunk
            # stream_options={
            #     "include_usage": True
            # }
)
print("\n" + "=" * 20 + "reasoning content" + "=" * 20 + "\n")

for chunk in completion:
      # If chunk.choices is empty, print usage
      if not chunk.choices:
          print("\nUsage:")
          print(chunk.usage)
      else:
        delta = chunk.choices[0].delta
        # Print reasoning content
        if hasattr(delta, 'reasoning_content') and delta.reasoning_content is not None:
           print(delta.reasoning_content, end='', flush=True)
           reasoning_content += delta.reasoning_content
        else:
           if delta.content != "" and is_answering is False:
              print("\n" + "=" * 20 + "content" + "=" * 20 + "\n")
              is_answering = True
        # Print content
        print(delta.content, end='', flush=True)
        content += delta.conten
消费级显卡即可本地部署
